In 1980, The Empire Strikes Back gave us one of the great bad ideas in movie history. Han Solo, chased by the Imperial fleet, flies the Millennium Falcon straight into an asteroid field. C-3PO reads out the odds of surviving it. Han’s answer is “Never tell me the odds.”
Plenty of SMB go-to-market teams run their programs the same way. The field is huge, the rocks all look alike, and the odds are sitting right there in the dashboard where nobody wants to read them.
The movie has a second lesson. When the Falcon finds a quiet cave to hide in, the cave turns out to be something else entirely. It looked like a safe place to land. It wasn’t. That is what a bad yes looks like in your funnel: it passes for a real account until you’re already inside it.
Selling to small businesses is that asteroid field. It’s huge, it’s cluttered, and a lot of what looks like a safe landing spot isn’t.
If you don’t disqualify correctly, your funnel numbers quietly fall apart, and nobody can tell you why.
Your reps still write good emails. Your ads still look fine. But conversion rates sink, the cost of each customer climbs, and the meeting where everyone tries to work out what happened ends with someone blaming the wrong thing.
This is why LeadGenius treats the ideal customer profile as an always-on engine, not a document you write once a year and file away. I’ll walk through how it works in plain words. But first I want to show you why the stakes are highest with small businesses, because that’s the part people underestimate.
The terms, in plain words
A few terms will come up again and again. Here they are in the simplest words I can find.
- SMB
- A small or medium business. The corner bakery, the three-truck plumbing company, the online shop run out of a garage.
- ICP
- Short for ideal customer profile. A picture of the customer you’d love more of. Not the biggest customer. The best one.
- Funnel
- A cone. Lots of possible customers go in the wide top, and fewer come out the narrow bottom as real customers. Pour in marbles and they roll out. Pour in mud and it clogs.
- Disqualify
- Deciding, with a reason, that an account shouldn’t be chased. A polite, well-supported no.
- Firmographics
- The basic facts about a company: industry, headcount, location, estimated revenue. Think of a name tag.
- Signal
- Something a business does that hints it may need you soon. Opening a new office. Hiring. Like seeing someone wipe their forehead and guessing they’re hot.
- Entity resolution
- Making sure you have the right business. There are a lot of Joe’s Pizzas in the world.
- SDR
- The person who does the first outreach and tries to book the first meeting.
The four questions
Every account you might chase deserves four questions.
| Question | What it asks and decides |
|---|---|
| Fit | Does this company have the operating traits that make our product valuable? Include it, exclude it, or give it a service tier. |
| Timing | Has something changed that makes the problem urgent now? Decides priority and message. |
| Reachability | Can we find and engage the right person or buying group? Decides channel and workflow. |
| Risk and economics | Is the account active, viable, within policy, and worth the cost of pursuit? Pursue, review, or suppress. |
Notice that these four do different jobs. Fit and risk decide whether an account belongs in your funnel at all. Timing only decides when. Reachability only decides how. A high-fit account with no reason to act right now isn’t bad. It’s early. Treat it like it’s bad and you’ve thrown away a customer you’ll want in three months.
This is also why I don’t trust one big score. A single number squashes four different answers together and hides which one is wrong.
Why small businesses make “no” so hard
Selling to a big public company is a bit like looking someone up in a phone book. They file reports. They have investor pages. They tell the whole world how many people work there and how much money they make.
Small businesses don’t. A ten-person online brand, a regional construction company, a fast-growing restaurant group, and a company that closed two years ago but still has a website and a registration on file can all slip through the same filter. Same industry bucket. Same headcount band. Same estimated revenue. Completely different customers. One of them isn’t a customer at all. It’s a ghost.
The facts about small businesses are scattered everywhere: their websites, job postings, social pages, online storefronts, review sites, local directories, trade publications, the news, licensing records, the software they run, and who owns them. No single source has the whole picture. So the hard part is not finding more names. The hard part is working out which business you’re looking at and what the scraps of evidence add up to.
The name-tag problem
Most teams build their SMB target list from name-tag facts: industry, headcount, location, estimated revenue. Those are the fields that happen to be available. They aren’t necessarily the fields that predict a good customer. And each one is shakier than it looks.
- Industry codes squash modern businesses into boxes that don’t fit. A shop that sells online, in stores, and wholesale gets one label.
- Headcount runs behind reality and misses contractors, franchise staff, seasonal workers, and people spread across different places.
- Estimated revenue is often a guess built on another guess, and it puts very different companies into the same broad band.
None of this makes name tags useless. They’re a fine first cut. But when they alone decide who’s qualified, the list looks precise because it has lots of columns and weak because those columns say little about whether a business is alive, ready to buy, or worth serving.
The clues that do predict a good customer are specific to what you sell. For payments, it might be checkout technology and a new location. For payroll, it might be hiring speed across states. A generic database can’t guess those for you.
Why a bad “yes” costs more with small businesses
You might ask whether every team has this problem. Sort of. But the math is different down here, for four reasons.
- There are a lot of them, and you can’t hand-check them. A team selling to big companies might work a few hundred accounts, and a person can research each one. A high-volume SMB program works far more. Nobody is reading every website. So rules do the deciding, and a bad rule repeats its mistake thousands of times.
- Each deal is small, so waste is a big slice. An hour spent working out whether a company is even real costs the same whether the deal is large or small. When the deal is small, that hour takes a much bigger bite out of what the deal is worth.
- The public information is thin. Fewer facts means more guessing, and guesses are where wrong yeses hide.
- Small businesses change fast. They open, close, move, hire, and get bought all the time. A list that was right in January can be wrong by summer.
Put those together. Lots of records, thin margins, foggy data, fast change. In that world a sloppy yes is the default, and it is expensive every single time.
Let me show you what it does to your numbers.
Try it: clog the funnel
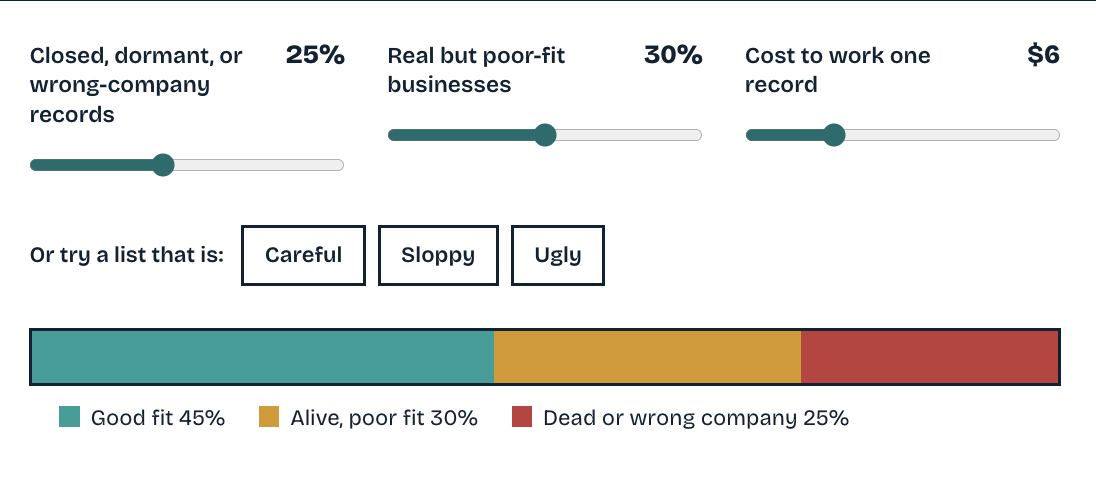
Below is a simple model. Same team. Same emails. Same skill. The only thing that changes is how much junk is in the list. The rates are made up to show the mechanics, so treat it as a toy, not a forecast.
- Good fit 45%
- Alive, poor fit 30%
- Dead or wrong company 25%
| Out of 10,000 records | Whole list | Good-fit only |
|---|---|---|
| Records worked | ||
| Total spend | ||
| Meetings booked | ||
| Customers won | ||
| Records to meeting | ||
| Meetings to customer | ||
| Cost per customer |
The made-up assumptions behind this toy
Good-fit business: 6 in 100 records become a meeting, 4 in 10 meetings become an opportunity, and 1 in 4 opportunities become a customer. Closed, dormant, or wrong-company records never become a meeting. Real but poor-fit businesses book meetings just as often, but only 2 in 10 meetings become an opportunity and 1 in 10 opportunities close. The model leaves out the extra cost of serving poor-fit customers and their churn, which would widen the gap. Plug in your own numbers before you believe any of this.
Look at the two right-hand columns. The first is what your dashboard says when you work the whole list. The second is what it would say if you had only worked the good-fit accounts. The team did nothing different, yet on the whole list records-to-meeting is lower, meetings-to-customer is lower, and each customer costs more. Two different things are happening, and they’re worth pulling apart.
The red part of the bar, the dead records, waters down the top of your funnel. The amber part, the alive but poor-fit businesses, is sneakier. They answer the phone. They take the meeting. Then they stall, or drag on, or close into customers who need a lot of help. That’s why the bottom of your funnel droops too.
One more thing to notice. At the starting settings, the good-fit-only column wins a few fewer customers, because a handful of poor-fit accounts do close. But it gets there for less than half the spend. Disqualifying isn’t about winning every last deal. It’s about not paying a lot to chase the ones that hurt you.
Five ways a bad “yes” poisons your numbers
It waters down the top of the funnel
Every rate at the top of a funnel is “good things that happened” divided by “records we worked.” Fill the bottom half of that fraction with businesses that can’t respond and the whole rate sinks. Your team looks slower. Nothing about the team changed.
It clogs the middle
Some bad yeses are alive, and that’s the dangerous kind, because a meeting looks like a win. Then the deal stalls, drags on, or becomes a customer who needs heavy support and doesn’t stick. Your meeting count looks great. Your meeting-to-customer rate droops and sales cycles get longer. And if you feed those customers back into your model as successes, the engine learns to go find more of them. Large contracts with heavy service needs can teach exactly the wrong lesson.
It makes your experiments lie
Say you test two subject lines, or two ad audiences. If a big slice of your list can never respond, both tests are partly measuring your list. Real differences get harder to see, and you may kill a good message because the list was bad.
It teaches sellers to ignore you
Reps notice a bad list fast. After a few dead ends they stop trusting recommendations and start doing their own research, or skip the queue. Now your routing rules and priority tiers go unused, you can’t tell whether the model works, and the research time you meant to save comes right back. One of the numbers I’d watch closely is how often sellers override the recommendation. A trusted no is what makes a yes believable.
It burns money and reputation
Ad spend goes to businesses that closed. Outreach goes to domains that went dark, and mail to dead addresses can hurt how inbox providers treat your future email. SDRs lose hours working out whether a company is even real. In high-volume SMB programs, removing inactive businesses, acquired companies, poor-fit models, and risky accounts can be as valuable as finding new names. It cuts wasted media, saves research time, and makes your conversion rates more honest.
A wrong “no” hurts too
Now for the part that keeps me honest. A no can be wrong.
Think about a bouncer at a party. If the bouncer lets in a stranger who breaks the furniture, that’s a wrong yes. If the bouncer turns away the host’s best friend because of her shoes, that’s a wrong no. A bouncer who says yes to everyone isn’t doing the job. Neither is one who says no to everyone. The whole skill is being right in both directions.
So what makes a no correct? Five habits.
- Check that the business is real before you judge it. Confirm the company, the live website, who owns it, where it operates. A smart score attached to the wrong domain or the wrong subsidiary is still wrong.
- Keep the evidence and the date. Every important fact should say where it came from, when it was seen, how sure we are, and whether a person looked at it. AI can scale a guess just as easily as it scales good research.
- Make hard stops hard. Active status, policy exclusions, and serious risk should work as gates, not as small negative points that a strong signal can outvote.
- Say “not yet” out loud. Timing defers. It never disqualifies. A good account with a weak trigger goes to nurture or monitoring, not the trash.
- Send the weird ones to a person. More on that below.
Where people belong in this
Human review is not a ceremonial last check. People decide what the business is trying to improve, choose which evidence counts, label hard examples, and judge whether a recommendation makes commercial sense. The trick is to send them the right work, based on risk and value, instead of spreading them evenly over every record. An analyst looks at:
- Conflicting evidence about who a company is or who owns it
- High-value accounts with missing or low-confidence facts
- Sensitive risk, compliance, or exclusion decisions
- Business models your current checklist doesn’t describe well
- Big score changes that would materially change spend or routing
- Random samples of automated decisions, to keep quality honest
You keep the speed of automation and put human judgment where mistakes cost the most. Every reviewed case also becomes a labeled example that makes the rules better next time.
The engine, in five stages
Here is how we build it. Five stages, each one producing something a person can inspect. And every stage, if you look closely, is really a way of getting better at saying no.
Stage one: start with your best customers
Not the biggest. The best. I’d look at three groups:
- The most profitable, after delivery, support, incentives, and channel costs.
- The happiest. They stay, expand, use the product, don’t need much hand-holding, and tell their friends.
- The easiest to win. Short cycles, high win rates, few people to convince, low cost to acquire.
Then split them by product, use case, region, customer type, and how you sold to them. A self-serve microbusiness and a multi-location mid-market customer teach different lessons, and mixing them hides both. One universal SMB ICP is usually less useful than several clear ones.
Here is the step most teams skip. Include the bad examples. Customers who churned, defaulted, barely used the product, needed constant support, or took forever to close. Add the deals that looked great and never converted. That’s where your disqualifiers come from.
Stage two: describe what makes them different
Name tags narrow the field. What makes an ICP yours is how a business actually runs and why it needs what you sell. That’s the proprietary part. Here are the families of facts we look at.
| Family of facts | Examples | Why it matters, in plain words |
|---|---|---|
| Business identity | Active status, website, ownership, parent companies, locations | Keeps you from attaching facts to the wrong company, and drops businesses that no longer operate. |
| Operating model | E-commerce, marketplace, franchise, subscription, field service, wholesale | Ties the account to the way your product is really used, which broad industry labels miss. |
| Commercial capacity | Transaction clues, location count, product breadth, customer volume | Tells you whether the business can support the contract or financial product you’d offer. |
| Growth and change | Hiring trends, new offices, launches, funding, leadership hires, partnerships | Shows momentum and possible buying windows. |
| Technology and process | Payments, commerce, CRM, ERP, marketing, security, logistics tools | Reveals compatibility, maturity, who you might replace, and how complicated their workflow is. |
| Risk and exclusions | Layoffs, closures, negative news, stale web presence, acquisition status, policy limits | Stops you from spending on accounts that are inactive, risky, or off-limits. This is where the no lives. |
| Buying group | Relevant roles, seniority, who owns each location, verified contacts | Turns an attractive company into an account you can actually act on. |
The best facts usually start as hunches from sales calls, implementation notes, win-loss reviews, customer success chats, and product data. A lender might find that new-office evidence predicts demand for credit. A workforce platform might find that hiring in several states creates urgency. A vertical software company might find that one scheduling or payment workflow is the best clue of fit. Write each hunch down as a field you can research and test.
Stage three: fill in the facts with evidence
Once you know what to track, you need the same facts for your customers, your prospects, your leads, and the wider market. That takes a research pipeline, not just a purchased database. It gathers evidence, cleans it up, dates it, and keeps track of where it came from.
- Resolve the entity first. Confirm the legal or operating company, the live domain, who owns it, the locations, and the business unit that matters.
- Collect evidence from many places. Company sites, job pages, social profiles, news, directories, public records, technology observations, and approved first-party or partner data.
- Sort the messy stuff into your checklist. Use machine learning and language models to classify unstructured content, and store the evidence and the date, not just the label.
- Make values comparable. Normalize them so accounts can be compared across regions, languages, business models, and sources.
- Have a person check the shaky ones. Ambiguous, high-value, sensitive, or low-confidence records get reviewed before they drive expensive action.
Stage four: turn facts into decisions
The output of all that research shouldn’t be a wider spreadsheet. It should be a set of decisions. We keep separate parts for fit, timing, reachability, and risk, so people can see the reason behind any ranking.
| Part | What goes in | What comes out |
|---|---|---|
| Fit | Operating model, use case, locations, capacity, technology compatibility | Tier A, B, or C, or excluded |
| Timing | How recent and strong the signals are: expansion, hiring, launches, ownership changes, funding | Act now, nurture, or monitor |
| Reachability | Buying roles covered, identity confidence, verified channel, who is responsible where | Sales-ready, marketing-only, partner route, or research needed |
| Risk and economics | Active status, negative signals, policy exclusions, cost to serve, expected account value | Pursue, manual review, or suppress |
You can blend the parts into a rank, and the weights should be learned from outcomes and owned by the business. A long, assisted sale might lean on fit. A high-volume outbound motion might lean on timing. But risk and policy exclusions? Those are gates, not weights.
Every recommendation should also come with a because, in plain words. A seller should be able to read: “Prioritized because they opened two locations, increased hiring, use a compatible commerce platform, and we have a verified operations leader.” That makes outreach more believable. It also lets the seller argue with a bad call.
Stage five: check again, and learn
Small businesses change faster than an annual workshop can keep up with. Websites go dark. Companies get bought. Headcount shrinks. New locations open. Decision makers move. So the engine reruns its research on a schedule that fits how fast each fact changes.
- Fast-moving signals like hiring, jobs, news, launches, and leadership changes: weekly or monthly.
- Slower facts like identity, ownership, active status, and technology: monthly or quarterly, with an extra check whenever something looks odd.
- High-value accounts and buying groups: more often, and deeper, than the long tail.
Every refresh records what changed and triggers a defined action: reprioritize, suppress, reroute, or change the message.
Two things follow that I really like. A yes can turn into a no: the closed shop you were about to email gets pulled before it costs anything. And a no can turn into a yes: the account that wasn’t ready opens a new office and jumps the line. A static list can do neither.
Then outcomes flow back in: wins, losses, expansion, churn, product adoption, late payments, support load, campaign response. A field that sounded smart in a workshop but shows no link to outcomes loses influence. A new pattern that keeps showing up among strong customers becomes a candidate. The ICP stops being a monument and becomes a hypothesis under constant review.
Does it work?
Here is what a study we did with Glass.ai found, working with a Fortune 500 bank that wanted to understand its small business customers. We watched fourteen signals of business change. Four mattered most: evidence of a new office, headcount growth over twelve months, current jobs advertised, and hiring-related news.
| What we compared | What we saw |
|---|---|
| Companies with signals present, across acquisition channels | 50 percent lift in booking rate |
| The same companies on proactive advertising channels | Nearly 80 percent lift in booking rate |
| New-office evidence, on proactively advertised channels | 160 percent increase in booking rate |
| Existing customers with signals present | More likely to increase spend, and fewer delinquencies over six months |
Read that last row again. The signals didn’t just find more buyers. They helped tell healthy small businesses from shaky ones. That’s disqualification working from both sides: knowing whom to chase, and whom to be careful with.
Please don’t copy those four signals or their weights. The lesson is that observable business change can improve decisions when it’s tied to your product, tested against your own outcomes, and watched consistently.
What changes for each team
Demand generation
You can stop buying lists and start building audiences. Pair fit with a specific event, then write the message around the reason you’re reaching out. A payroll campaign might go to multi-state employers whose hiring is speeding up. A payments campaign might go to commerce businesses that are adding locations. A commercial insurance campaign might focus on companies expanding into places with new coverage requirements. And treat suppression as a feature. Every dead or poor-fit account you remove is money and attention you keep.
Revenue operations
RevOps turns data into workflow. Define the fields, which source wins when sources disagree, how confident a fact must be, how often it’s refreshed, and the routing rules, service levels, and audit process. Keep what was observed separate from what was guessed, and write the reason code and date into the systems where people already work. Then the rules can be plain:
- Route to Sales when fit, timing, and contact coverage clear agreed thresholds.
- Send to nurture when fit is high but timing is weak.
- Send for research when value is high but identity is uncertain.
- Suppress when active status or policy checks fail.
Sales
Sales gets a ranked territory with a reason to call. Reps spend less time deciding whether a company is real and more time preparing something worth saying. Managers can check whether the signal behind each recommendation actually led to conversations, opportunities, and revenue.
The first ninety days
Pick one product and one market, and work through six steps. Each ends with a question you have to answer honestly before moving on.
-
Days 1 to 15
Pick one product and one market. Decide what “profitable,” “happy,” and “efficient” mean for you. Gather good examples and bad ones.
You end with: a starting group of customers and a written definition of the outcome you want. The gate: does this group represent the motion we want to improve?
-
Days 16 to 30
Talk to Sales, Marketing, RevOps, Customer Success, Risk, and Product. Write down the facts you’ll track and the rules for what counts as evidence, including the exclusions.
You end with: a dictionary of attributes with evidence rules. The gate: can we observe or work out each important fact the same way every time?
-
Days 31 to 50
Resolve the entities. Enrich the starting group plus a representative sample of prospects.
You end with: a research dataset backed by evidence. The gate: are coverage, confidence, and cost per record acceptable?
-
Days 51 to 65
Test the attributes against wins, losses, retention, expansion, service cost, and campaign response.
You end with: a first model for fit, timing, reachability, and risk. The gate: do the chosen attributes beat plain filters?
-
Days 66 to 80
Run one controlled audience or seller workflow, with reason codes and human review.
You end with: a pilot campaign and a playbook. The gate: can people understand and act on the recommendation?
-
Days 81 to 90
Measure the results, review the errors, tune the thresholds, and set refresh schedules.
You end with: a roadmap for production and a rhythm for governance. The gate: is there enough extra value to scale?
How to keep score
The scoreboard is not how many fields you filled in. A complete but weak record doesn’t improve a decision. Measure the chain from data to behavior to money.
| Layer | What to track |
|---|---|
| Data quality | Entity match accuracy, active-company precision, field coverage, confidence spread, source recency, how often human reviewers disagree |
| Decision quality | Precision within priority tiers, false-positive rate, suppression accuracy, ranking lift over baseline, stability and drift |
| Workflow | Research time saved, routing acceptance, speed to action, seller override rate, audience activation rate, contact coverage |
| Commercial | Meeting and booking rate, conversion, sales cycle, acquisition cost, spend efficiency, retention, expansion, service cost, risk outcomes |
Notice that the second row is where you measure your no’s: suppression accuracy and false-positive rate. If you never check whether your no’s were right, you’re only grading half the test.
Whenever you can, use a holdout, a group you leave alone so you have something honest to compare against. Measure the extra value over your current firmographic approach, not just the raw result. Then look at outcomes by segment, so a strong average doesn’t hide a failure in one region, business model, or customer tier.
Eight ways this goes wrong
An always-on engine can fail even when the technology works. The usual problems are operational.
- Starting with revenue instead of customer economics. A big contract that eats your support team teaches the wrong pattern.
- Learning only from the winners. Without churned, unprofitable, risky, and lost examples, the engine can’t learn what to exclude.
- Mistaking a pattern for a cause. Signals should improve prediction and priority. Don’t invent a story the evidence doesn’t support.
- Automating before agreeing on what the words mean. Faster collection doesn’t help when two teams define the same field differently.
- Skipping entity resolution. A sophisticated score on the wrong company is still wrong.
- Hiding everything inside one score. People need the parts, the evidence, the dates, and the reasons.
- Refreshing everything at the same speed. Jobs and news move fast. Ownership and identity move slowly. They need different schedules.
- Counting records instead of decisions. Coverage is an input. Lift and less waste are the outcomes.
Where I land
The future of B2B data is not another prebuilt lake of generic records. Small business markets make the limits of that model obvious. The useful evidence is scattered, always moving, and specific to whatever you sell. No provider can guess every company’s best ICP attributes and freeze them into one universal database.
So we build the dataset around your decision. That can mean resolving a difficult global market, defining a taxonomy for your product, watching public business change, finding the right buying roles, putting human research on the ambiguous records, and delivering the result into the tools your team already uses. The goal isn’t more data. It’s a defensible reason to pursue, prioritize, personalize, or suppress each account.
The team that wins isn’t the one that contacts the most businesses. It’s the one that knows which ones not to contact, can say why, and checks again next month.
For teams that sell to small businesses, that is the difference between buying a list and building an advantage.
Want to see this on your own market?
Tell us what you sell and who you want more of. We’ll show you what an evidence-backed ICP looks like for your accounts, including the ones we’d say no to.
Connect with a strategist Request a free data sampleSource note. The financial-services case study and signal examples in this article come from LeadGenius and Glass.ai, AI LLMs The X Factor Innovation Unlocking the SMB Market for the Financial Services Sector. Reported lifts describe the study presented in that paper and should not be treated as guaranteed outcomes for other programs. The funnel calculator uses made-up rates for illustration only.